下面是公开课的回顾(因时长关系,视频分成了上下两部分):
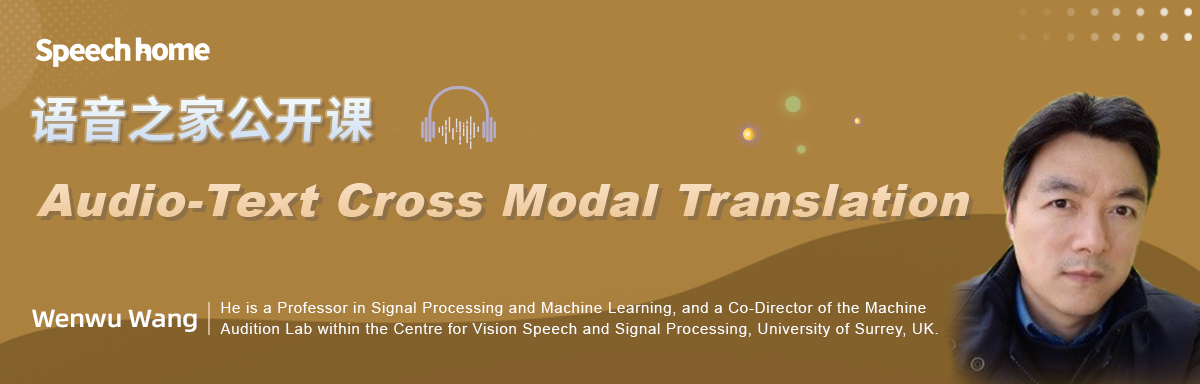
Cross modal translation of audio and texts has emerged as an important research area in artificial intelligence, sitting at the intersection of audio signal processing and natural language processing. Generating a meaningful description for an audio clip is known as automated audio captioning, which is useful in applications such as assisting the hearing-impaired to understand environmental sounds, facilitating retrieval of multimedia content, and analyzing sounds for security surveillance. Generating audio with text prompts is known as text-to-audio generation, which can be used as sound synthesis tools for film making, game design, virtual reality/metaverse, digital media, and digital assistants for text understanding by visually impaired. Cross modal audio-text translation requires understanding of the audio events and scenes in an audio clip, and the textual information as natural language, and learning the mapping and alignment of these two streams of information. Exciting new developments have emerged recently in automated audio-text cross modal translation. In this talk, we will give a brief introduction of this field, including problem description, potential applications, datasets, open challenges, recent technical progresses, and finally, possible future research directions.
至此,本期公开课圆满结束。语音之家将持续为大家带来干货满满的技术分享,敬请关注!