语音小管家
针对Grad-TTS提出两个问题:
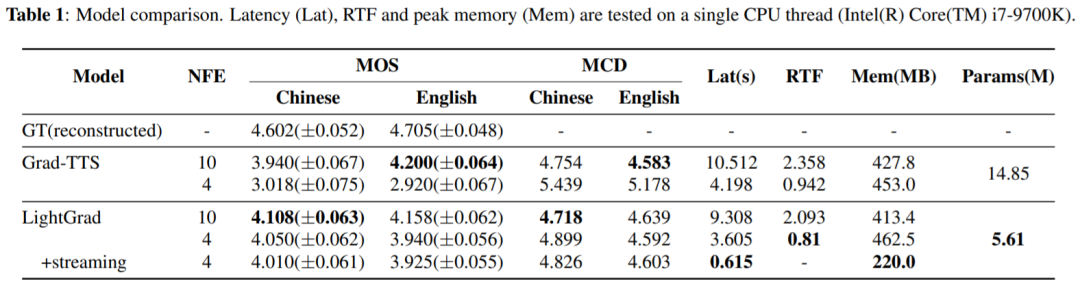
DPMs are not lightweight enough for resource-constrained devices. DPMs require many denoising steps in inference, which increases latency.
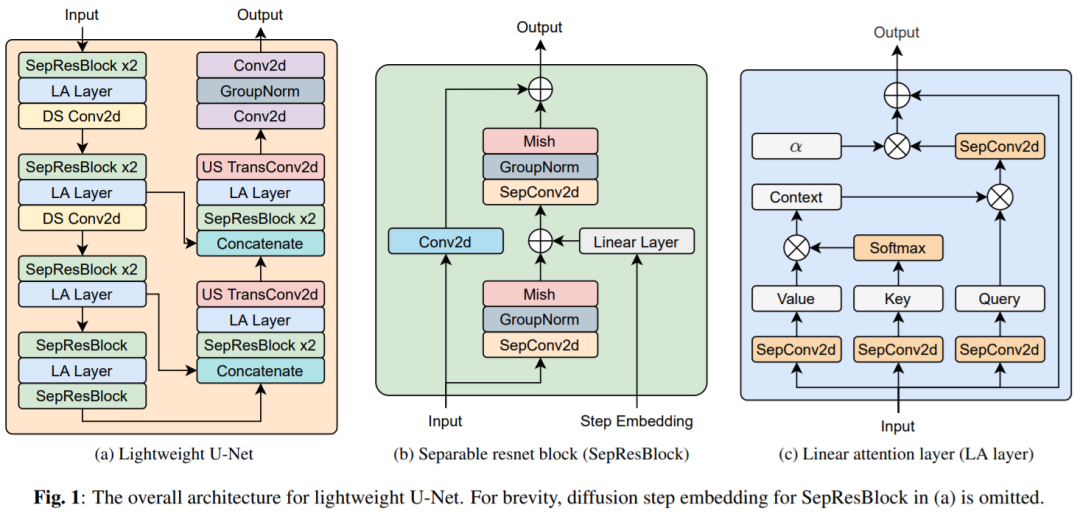
To reduce model parameters, regular convolution networks in diffusion decoder are substituted withdepthwise separable convolutions. To accelerate the inference procedure, we adopt a training-free fast sampling technique for DPMs (DPM-solver). Streaming inferenceis also implemented in LightGrad to reduce latency further.
具体实现:
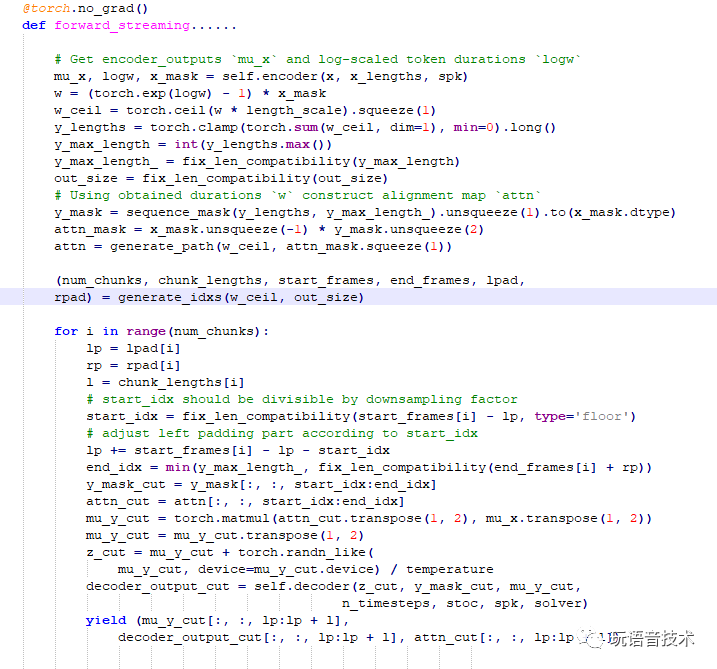
Decoder input is chopped into chunks at phoneme boundaries to cover several consecutive phonemes and the chunk lengths are limited to a predefined range. To incorporate context information into decoder, last phoneme of the previous chunk and first phoneme of the following chunk are padded to the head and tail of the current chunk. Then, the decoder generates mel-spectrogram for each padded chunk. After this, mel-spectrogram frames corresponding to the padded phonemes are removed to reverse the changes to each chunk.