
 语音小管家
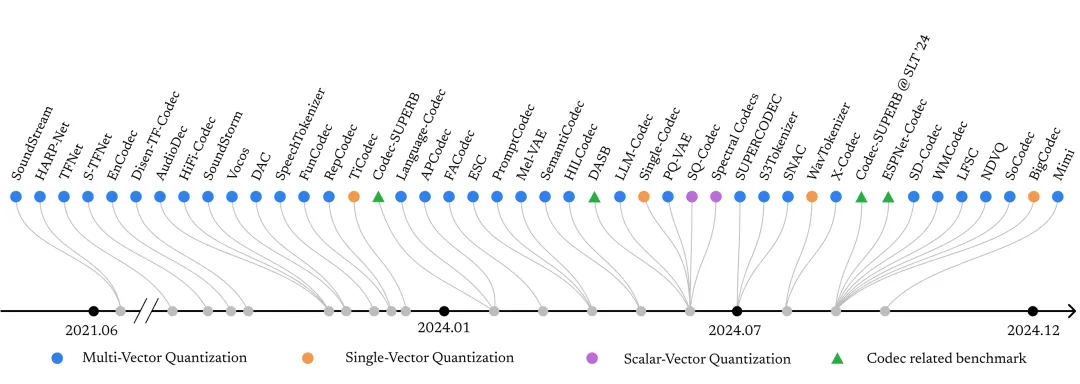
我们报告的部分录影和报告幻灯片会更新在以下两个网站
Host
Haibin Wu(微软):https://hbwu-ntu.github.io/
演讲人介绍
1、Academia
Prof. Wenwu Wang
演讲主题:Neural Audio Codecs: Recent Progress and a Case Study with SemantiCodec
摘要:The neural audio codec has attracted increasing interest as a highly effective method for audio compression and representation. By transforming continuous audio into discrete tokens, it facilitates the use of large language modelling (LLM) techniques in audio processing. In this talk, we will report recent progress in neural audio codecs, with a particular focus on SemantiCodec, a new neural audio codec for ultra-low bit rate audio compression and tokenization. SemantiCodec features a dual-encoder architecture: a semantic encoder using a self-supervised AudioMAE, discretized using k-means clustering on extensive audio data, and an acoustic encoder to capture the remaining details. The semantic and acoustic encoder outputs are then used to reconstruct audio via a diffusion-model-based decoder. SemantiCodec presents several advantages over previous codecs, which typically operate at high bitrates, are confined to narrow domains like speech, and lack the semantic information essential for effective language modelling. First, SemantiCodec compresses audio into fewer than 100 tokens per second across various audio types, including speech, general audio, and music, while maintaining high-quality output. Second, it preserves substantially richer semantic information from audio compared to all evaluated codecs. We will illustrate these benefits through benchmarking and conclude by discussing potential directions for future research in this field.
讲者介绍:Wenwu Wang is a Professor in Signal Processing and Machine Learning, University of Surrey, UK. He is also an AI Fellow at the Surrey Institute for People Centred Artificial Intelligence. His current research interests include signal processing, machine learning and perception, artificial intelligence, machine audition (listening), and statistical anomaly detection. He has (co)-authored over 300 papers in these areas. He has been recognized as a (co-)author or (co)-recipient of more than 15 accolades, including the 2022 IEEE Signal Processing Society Young Author Best Paper Award, ICAUS 2021 Best Paper Award, DCASE 2020 and 2023 Judge’s Award, DCASE 2019 and 2020 Reproducible System Award, and LVA/ICA 2018 Best Student Paper Award. He is an Associate Editor (2020-2025) for IEEE/ACM Transactions on Audio Speech and Language Processing, and an Associate Editor (2024-2026) for IEEE Transactions on Multimedia. He was a Senior Area Editor (2019-2023) and Associate Editor (2014-2018) for IEEE Transactions on Signal Processing. He is the elected Chair (2023-2024) of IEEE Signal Processing Society (SPS) Machine Learning for Signal Processing Technical Committee, a Board Member (2023-2024) of IEEE SPS Technical Directions Board, the elected Chair (2025-2027) and Vice Chair (2022-2024) of the EURASIP Technical Area Committee on Acoustic Speech and Music Signal Processing, an elected Member (2021-2026) of the IEEE SPS Signal Processing Theory and Methods Technical Committee. He has been on the organising committee of INTERSPEECH 2022, IEEE ICASSP 2019 & 2024, IEEE MLSP 2013 & 2024, and SSP 2009. He is Technical Program Co-Chair of IEEE MLSP 2025. He has been an invited Keynote or Plenary Speaker on more than 20 international conferences and workshops.
Prof. Minje Kim
演讲主题:Future Directions in Neural Speech Communication Codecs
摘要:Neural speech codecs promise high-quality speech at low bitrates but face challenges like increased model complexity and suboptimal quality. This talk presents two approaches to address these issues: generative de-quantization and personalization. With LaDiffCodec, we propose separating representation learning from information reconstruction. It combines a typical end-to-end codec that learns low-dimensional discrete tokens for compact representation and a latent diffusion model that de-quantizes these tokens into high-dimensional continuous space in a generative fashion. To prevent over-smooth speech, we employ “midway-infilling” during diffusion. Subjective tests show our model improves popular neural speech codecs' performance. Next, we introduce personalized neural speech codecs, where we explore personalizing codecs to specific user groups to reduce complexity and enhance perceptual quality. By learning speaker embeddings with a Siamese network from the LibriSpeech dataset, we cluster speakers based on perceptual similarity. Subjective tests reveal this strategy enables model compression without sacrificing—and even improving—speech quality. By decoupling key tasks and introducing personalization, these approaches address current limitations and pave the way for superior speech quality and efficiency at low bitrates in neural speech codecs.
讲者介绍:
Dongchao Yang
演讲主题
摘要
讲者介绍:Dongchao Yang is a second-year Ph.D. student at The Chinese University of Hong Kong, supervised by Prof. Helen Meng. Before that, he received his master's degree from Peking University. His research interests encompass the extensive domain of speech and language intelligence, which includes audio foundation models, multi-modal large language models (MLLMs), text-to-speech synthesis (TTS), cross-modal representation learning, among other related areas. Currently, his work focuses on audio-text foundation models and audio codec models.
Dr. Shang-Wen Li
Dr. Neil Zeghidour
摘要:Audio analysis and audio synthesis require modeling long-term, complex phenomena and have historically been tackled in an asymmetric fashion, with specific analysis models that differ from their synthesis counterpart. In this presentation, we will introduce the concept of audiolanguage models, a recent innovation aimed at overcoming these limitations. By discretizing audiosignals using a neural audio codec, we can frame both audio generation and audio comprehension as similar autoregressive sequence-to-sequence tasks, capitalizing on the well-established Transformer architecture commonly used in language modeling. This approach unlocks novel capabilities in areas such as textless speech modeling, zero-shot voice conversion, text-to-music generation and even real-time spoken dialogue. Furthermore, we will illustrate how the integration of analysis and synthesis within a single model enables the creation of versatile audio models capable of handling a wide range of tasks involving audio as inputs or outputs. We will conclude by highlighting the promising prospects offered by these models and discussing the key challenges that lie ahead in their development.
讲者介绍:Founded Kyutai in Paris. Previously Staff Research Scientist at Google DeepMind. Teaching "Algorithms for Speech and Natural Language Processing" at master MVA (École Normale Supérieure). Interested in deep learning for audio understanding, audio synthesis, and signal processing.
