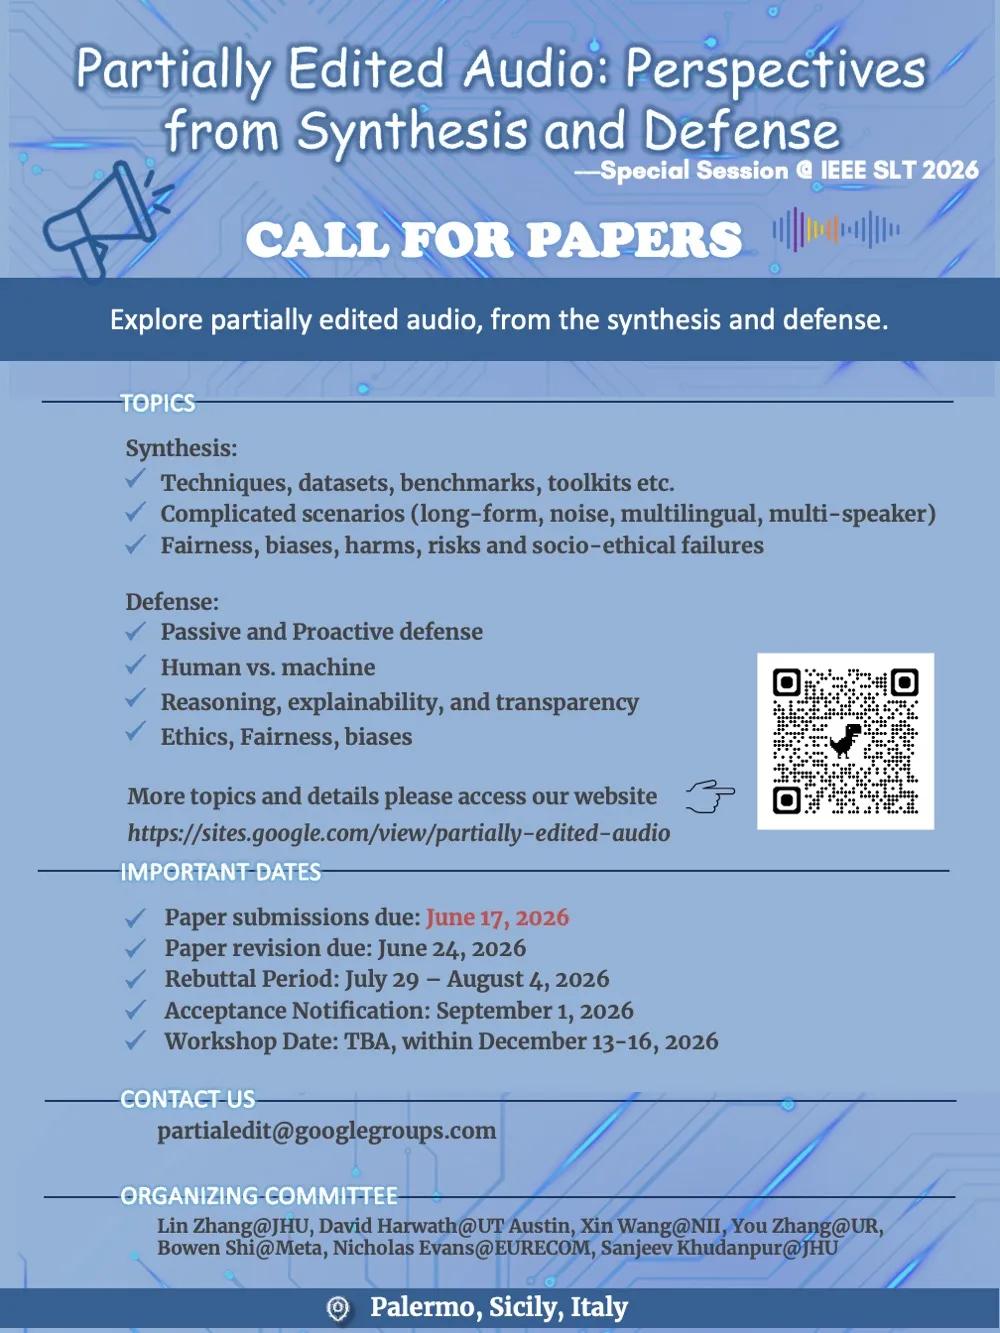
我们诚挚邀请您投稿至IEEE SLT2026特别议题:“Partially Edited Audio: Perspectives from Synthesis and Defense” 本次会议将于12月在意大利西西里举行。本特别议题聚焦于一个新兴且重要的方向:部分篡改语音。旨在从合成(Synthesis)与检测(Defense)两个角度,推动该领域的发展。我们欢迎来自学术界与工业界的研究人员积极投稿。
官方网站:https://sites.google.com/view/partially-edited-audio
背景介绍
随着深度学习和生成式人工智能的快速发展,语音的生成与编辑变得前所未有地便捷。在语音合成领域,诸如VoiceBox、A3T、SpeechX 和 VoiceCraft 等语音编辑算法,使得缺乏专业技能的用户也能以极低门槛生成高度逼真的音频内容。这些工具支持对已有语音中的特定片段进行精准修改,而无需改变整段录音,从而省去重新录制整句的麻烦。例如,用户只需编辑出错的词语或音节,就能纠正发音,而不必重新生成整段音频。
尽管语音编辑技术具有重要的正向应用价值,但其潜在的滥用风险同样不容忽视,包括:篡改公众人物的讲话、误导声纹识别系统,以及实施电信与金融欺诈等。更具挑战的是,编辑后的语音往往包含大量未被篡改的真实片段,这会干扰检测模型的判断,从而显著增加识别与追踪操控痕迹的难度。
本专题旨在探讨“部分编辑”的音频/语音/音乐/歌唱等内容所带来的新兴挑战,并推动合成与防御两大社区的交流与合作。
征稿方向
包括但不限于
Synthesis:
- Techniques for partially editing content/background/emotion/prosody/object/etc. of audio/speech/music/singing or multimodal audio-visual media.
- Methods to ensure acoustic and perceptual consistency after editing
- Datasets, benchmarks, toolkit for partial audio/speech editing
- Unified models for zero-shot TTS (continuation) and speech editing (infilling)
- Partially audio/speech editing for more complicated scenarios, like long-form and/or multi-speaker conversations, noisy background, multilingual editing, etc.
- Fairness, biases, harms, risks and socio-ethical failures of partial editing.
Defense:
- Detection, localization, and diarization of partially edited audio
- Proactive protecting under partial edits, like watermarking
- Adaptation and generalization methods for identifying edits
- Human vs. machine performance in detecting partially edited audio
- Explainability, interpretability and transparency techniques for defense against partial edits in speech
- Ethics of data collection, annotation, and use of data for speech editing.
- Fairness, biases for defending against audio/speech/music/singing editing.
- Joint defense against partial editing with other downstream tasks, like ASV, ASR, etc.
Other novel topics related to audio/speech/music/singing editing
重要时间节点
与 IEEE SLT2026 同步, 以 AoE 时间为准
| 投稿截止 | 2026.6.17 |
| 论文修订截止 | 2026.6.24 |
| 论文rebuttal | 2026.7.29 –8.4 |
| 录用通知 | 2026.9.1 |
| 最终稿截止 | 2026.9.16 |
| 会议日期 | 待定,12.13~16中某天 |
我们诚邀您分享最新研究成果,携手探索部分篡改语音的生成和检测的未来!
组织团队
- Dr. Lin Zhang 张琳(Johns Hopkins University, USA)
- Prof. David Harwath (UT Austin, USA)
- Prof. Xin Wang 王鑫(NII, Japan)
- Dr. You Zhang 张优(University of Rochester, USA)
- Dr. Bowen Shi 施博文(Meta, USA)
- Prof. Nicholas Evans(EURECOM, France)
- Prof. Sanjeev Khudanpur(Johns Hopkins University, USA)