INTERSPEECH 2026 论文预讲会由中国中文信息学会、CCF语音对话与听觉专委会、深圳市人工智能学会、语音之家发起,旨在为学者们提供更多的交流机会,更方便、快捷地了解领域前沿。活动将邀请 INTERSPEECH 2026 录用论文的作者进行报告交流。
INTERSPEECH 2026 论文预讲会第六期邀请到西交利物浦大学听觉智能计算课题组做本次会议的专场分享,欢迎大家观看。
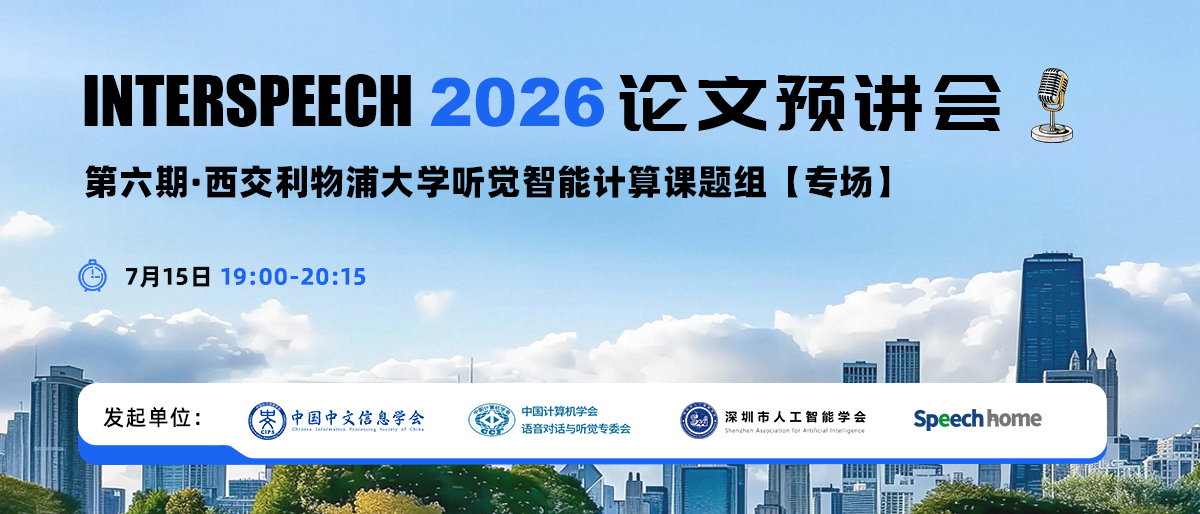
第六期-西交利物浦大学听觉智能计算课题组【专场】
时间:7月15日(周三)19:00 ~ 20:15
形式:线上
议程:每位嘉宾分享25分钟(含5分钟QA)
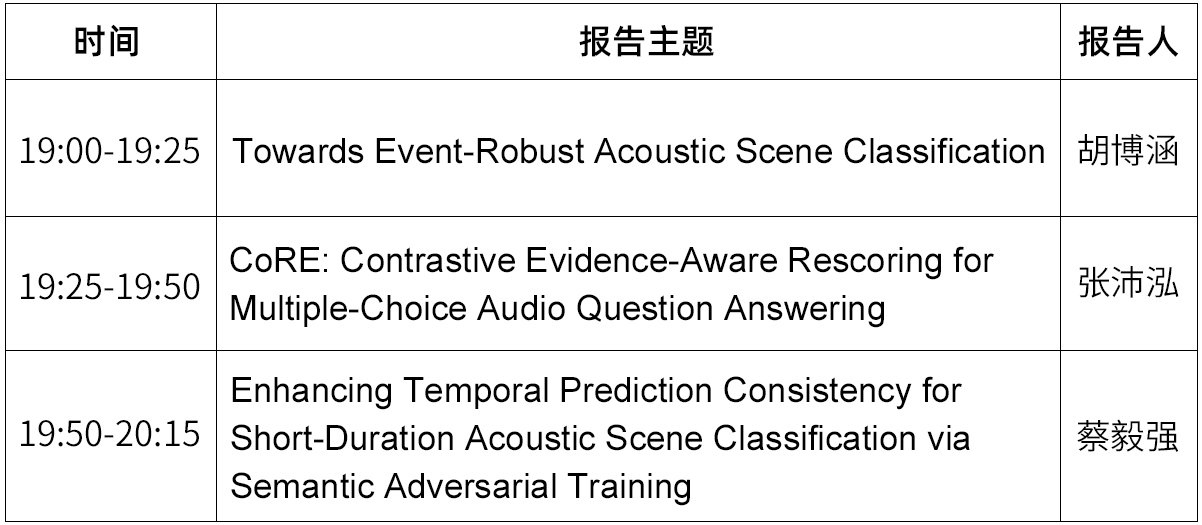
嘉宾&主题
嘉宾简介:胡博涵,西交利物浦大学(XJTLU)在读本科生,主要研究方向聚焦AI声学感知、持续增量学习、域偏移泛化。
报告题目:Towards Event-Robust Acoustic Scene Classification
摘要:This paper introduces the Event-Shifted Acoustic Scene (ESAS) dataset, a novel benchmark for evaluating the robustness of Acoustic Scene Classification (ASC) systems against unknown sound events. Existing ASC datasets typically contain recordings of clean and consistent audio, while real-world environments often include diverse and unexpected sound events. To bridge this gap, ESAS simulates real-world acoustic variability by injecting foreground sound events into background scenes with the assistance of large language models. In this work, we present the construction methodology, dataset statistics, and evaluation protocols. Furthermore, a comprehensive evaluation of state-of-the-art ASC systems is conducted using the ESAS benchmark. Experimental results reveal that existing ASC models suffer significant performance degradation when facing the event-shift challenge. The introduction of the ESAS dataset aims to drive future research toward event-robust ASC.
论文链接:https://arxiv.org/abs/2606.06921
数据集链接:https://zenodo.org/records/20623264
嘉宾简介:张沛泓,西交利物浦大学二年级博士研究生,研究方向为音频域泛化与音频大模型幻觉问题,多篇论文发表在ICASSP、InterSpeech、ICME等国际学术会议。
报告题目:CoRE: Contrastive Evidence-Aware Rescoring for Multiple-Choice Audio Question Answering
摘要:Large Audio-Language Models (LALMs) achieve strong performance on multiple-choice Audio Question Answering (AQA) but often exhibit modality bias, over-relying on textual priors in questions and candidate options rather than grounded acoustic evidence. We present CoRE, a training-free, plug-and-play test-time option re-scoring method. CoRE constructs counterfactual audio via chunk permutation and random segment reversal to disrupt long-range temporal structure while largely preserving short-time acoustics. It estimates option-level evidence gain by contrasting scores from original and counterfactual audio, and applies an adaptive evidence-aware gate for final prediction. Under a unified option-scoring protocol, experiments on DCASE 2025 Task 5 and AIR-Bench SoundQA show consistent gains with Qwen2-Audio and Kimi-Audio.
嘉宾简介:蔡毅强,西交利物浦大学四年级博士研究生,研究方向为音频算法化简与领域泛化。
报告题目:Enhancing Temporal Prediction Consistency for Short-Duration Acoustic Scene Classification via Semantic Adversarial Training
摘要:Short-duration Acoustic Scene Classification (ASC) is essential for building responsive environmental sensing systems. However, standard ASC models show severe performance collapse when restricting to short observation windows. Our study reveals that the degradation stems from temporal prediction inconsistency—a misalignment between the global scene context and the model’s local predictions. To address this, we propose the Semantic Adversarial Training (SAT) framework. SAT introduces an auxiliary adversarial objective that competes with the standard scene classification task, forcing the feature extractor to discard duration-dependent semantic variances while learning scene-discriminative features. Experimental results demonstrate a direct correlation between local-global prediction discrepancy and model accuracy. Crucially, SAT significantly mitigates the performance drop on high-discrepancy samples, yielding a more robust and temporally consistent ASC system.
参与方式
直播将通过语音之家微信视频号进行直播
手机端、PC端可同步观看
👇👇👇
预讲会征集
INTERSPEECH 2026 论文预讲会面向全球线上招募,结合定向邀请与征集报名的方式,来选择预讲会的嘉宾。
为了共创高质量的论文预讲会,我们诚挚邀请所有 INTERSPEECH 2026 作者参与到此次预讲会活动中来,也欢迎大家推荐适合此次预讲会活动的学者。