分享
Deeply Korean read speech corpus contains pairs of Korean speakers reading a script with 3 distinct text sentiments , with 3 distinct voice sentiments are recorded.
A dataset of over 700 different languages providing audio, aligned text and word pronunciations.
An Open-Source Non-native English Speech Corpus For Pronunciation Assessment
Dataset based on Twitter usernames of American politicians. Data extracted from Wikidata.
Cambridge Well-being Dataset for Psychological Distress Analysis
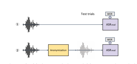
VoicePrivacy 2020 is a dataset for developing anonymization solutions for speech technology. It is built from subsets of existing datasets such as: LibriSpeech, LibriTTS, VoxCeleb1,VoxCeleb2 and VCTK.
The Arabic Speech Corpus (1.5 GB) is a Modern Standard Arabic (MSA) speech corpus for speech synthesis.
Voice Navigation is a large-scale dataset of Chinese speech for slot filling, containing more than 830,000 samples.