我的资源
共 246 个数据集
Interview
NLP
Interview

Introduced by Majumder et al. inInterview: A Large-Scale Open-Source Corpus of Media Dialog

0 下载 · 0 赞获取 →
BD-4SK-ASR
Speech Recognition
BD-4SK-ASR

Introduced by Qader et al. in Kurdish (Sorani) Speech to Text: Presenting an Experimental Dataset

0 下载 · 0 赞获取 →
GUM
Named Entity RecognitionEntity Linking
GUM

GUM is an open source multilayer English corpus of richly annotated texts from twelve text types.

0 下载 · 0 赞获取 →
DISRPT2021
Relation ClassificationDiscourse Parsing
DISRPT2021

DISRPT2021 shared task on Discourse Unit Segmentation, Connective Detection and Discourse Relation Classification

0 下载 · 0 赞获取 →
TaL Corpus
Speech RecognitionSpeech Synthesis
TaL Corpus

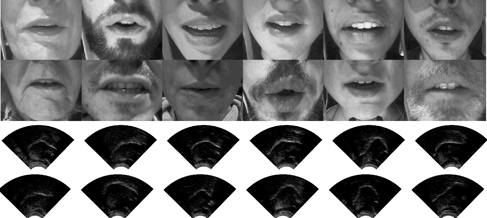
The Tongue and Lips (TaL) corpus is a multi-speaker corpus of ultrasound images of the tongue and video images of lips.

0 下载 · 0 赞获取 →
VoxForge
Keyword SpottingSpoken language identification
VoxForge

VoxForge is an open speech dataset that was set up to collect transcribed speech for use with Free and Open Source Speech Recognition Engines (on Linux, Windows and Mac).

0 下载 · 0 赞获取 →
SPGISpeech
SPGISpeech

Introduced by O'Neill et al. in SPGISpeech: 5,000 hours of transcribed financial audio for fully formatted end-to-end speech recognition

0 下载 · 0 赞获取 →
ClovaCall
Speech RecognitionGoalOriented Dialog
ClovaCall

Introduced by Ha et al. in ClovaCall: Korean Goal-Oriented Dialog Speech Corpus for Automatic Speech Recognition of Contact Centers

0 下载 · 0 赞获取 →
TUDA
Speech Recognition
TUDA

Introduced by Radeck-Arneth et al. in Open Source German Distant Speech Recognition: Corpus and Acoustic Model

0 下载 · 0 赞获取 →
ESD (Emotional Speech Database
Voice Conversion
ESD (Emotional Speech Database

Introduced by Zhou et al. in Emotional Voice Conversion: Theory, Databases and ESD

0 下载 · 0 赞获取 →
MRDA
Dialogue Act Classification
MRDA

The MRDA corpus consists of about 75 hours of speech from 75 naturally-occurring meetings among 53 speakers.

0 下载 · 0 赞获取 →
SPEECH-COCO
Speech RecognitionIntent Detection
SPEECH-COCO

Introduced by Havard et al. in SPEECH-COCO: 600k Visually Grounded Spoken Captions Aligned to MSCOCO Data Set

0 下载 · 0 赞获取 →