
分享
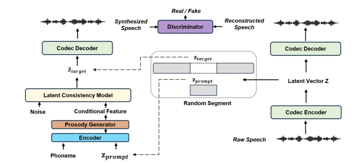
由香港科技大学和微软联合开发的 FlashSpeech 模型,在零样本语音合成领域取得了显著进展。这款基于潜在一致性模型Latent Consistency Model的系统,不仅在语音合成速度上实现了20倍速度的飞跃,音质和相似度上却可以在与现有SOTA持平。
Fluency TTS 8.0 is een compleet nieuwe implementatie van deze populaire spraaksynthesizer, die nu ook ondersteuning biedt voor 64-bit programma's en 64-bit SAPI.
清华大学语音处理与机器智能实验室(THU-SPMI)推出了基于CTC-CRF的ASR工具包CAT,在多个基准数据集上取得了前沿性能(State-Of-The-Art,SOTA)。近期CAT工具包有了较大改动,升级版本命名为CAT-v2
Transducersaurus is a module which builds component WFSTs for Automatic Speech Recognition Cascades (ASR). It contains classes suitable for building language model transducers from ARPA format LMs,
This tar file contains perl scripts designed to manipulate speech database transcriptions and word lattice files.
This module installs a subset of the CMU Sphinx python libraries which can be used to read in binary format Sphinx Acoustic Models.