
 新一代Kaldi
文章来源于新一代Kaldi,作者NGK编辑部
相关代码:https://github.com/k2-fsa/icefall/blob/master/egs/librispeech/ASR/pruned_transducer_stateless2/scaling.py#L115
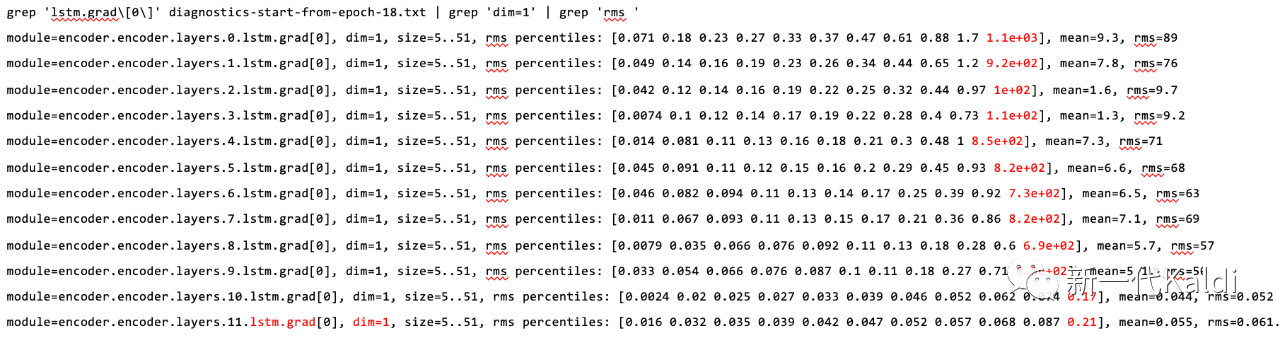
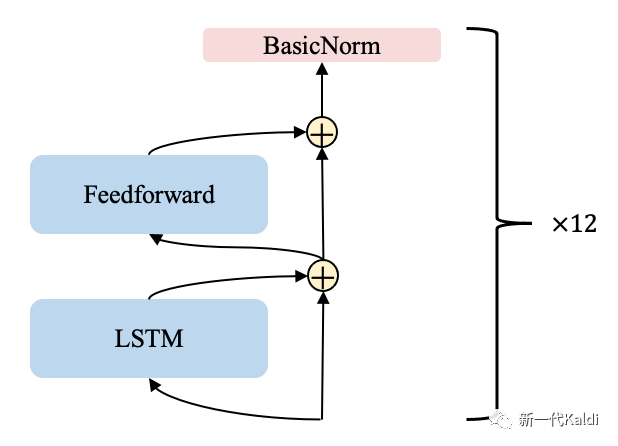
1. LSTM 梯度问题
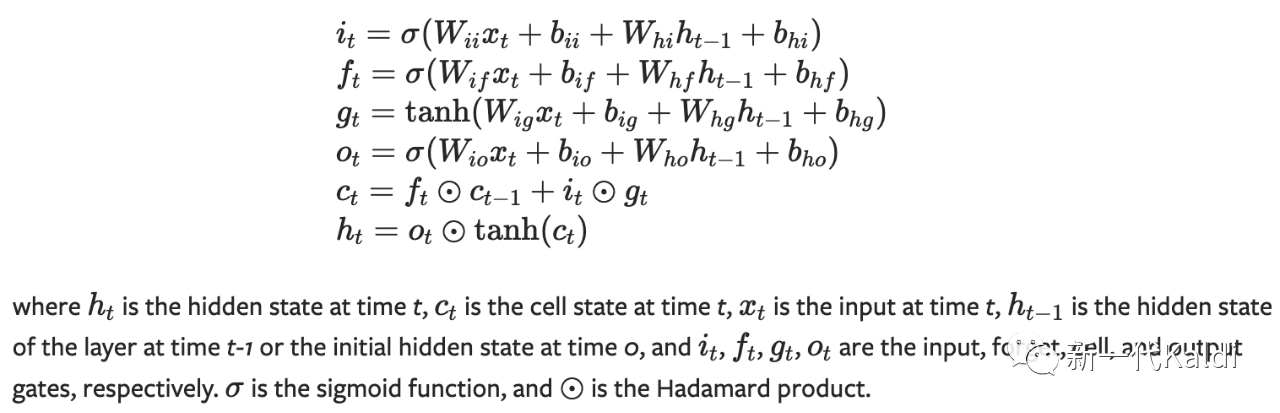
2. Pytorch 中的 clip_grad_norm_
torch.nn.utils.clip_grad_norm_可以在一定程度上解决梯度爆炸的问题,然而,该函数作用于对整个模型梯度反向传播结束之后,核心代码如下所示。# see https://github.com/pytorch/pytorch/blob/435e78e5237d9fb3e433fff6ce028569db937264/
torch/nn/utils/clip_grad.py#L10total_norm = torch.norm(
torch.stack(
[torch.norm(p.grad.detach(), norm_type).to(device)forpinparameters]
), norm_type
)
clip_coef = max_norm / (total_norm + 1e-6)
clip_coef_clamped = torch.clamp(clip_coef, max=1.0)
for p inparameters:
p.grad.detach().mul_(clip_coef_clamped.to(p.grad.device))裁剪之后,那些发生爆炸的模块会占主导,其它模块的梯度将变得特别小; 爆炸的梯度向前面层反向传播没有太大意义。
3. GradientFilter
# see https://github.com/k2-fsa/icefall/blob/9b671e1c21c190f68183f05d33df1c134079ca18/egs/librispeech/ASR/pruned_transducer_stateless2/scaling.py#L594
input, *flat_weights = self.grad_filter(input, *flat_weights)过滤每个 batch 中发生梯度爆炸的那些元素(序列); 并根据梯度裁剪的程度,对应地放缩 LSTM 模块参数的梯度。
# see https://github.com/k2-fsa/icefall/blob/9b671e1c21c190f68183f05d33df1c134079ca18/egs/librispeech/ASR/pruned_transducer_stateless2/scaling.py#L115
eps = 1.0e-20
dim = ctx.batch_dim
norm_dims = [dfordinrange(x_grad.ndim)ifd != dim]
norm_of_batch = (x_grad ** 2).mean(dim=norm_dims, keepdim=True).sqrt()
median_norm = norm_of_batch.median()

# filter gradients of batch elements
cutoff = median_norm * ctx.threshold
inv_mask = (cutoff + norm_of_batch) / (cutoff + eps)
mask = 1.0 / (inv_mask + eps)
x_grad = x_grad * mask

# filter gradients of module parameters
avg_mask = 1.0 / (inv_mask.mean() + eps)
param_grads = [avg_mask * gforginparam_grads]
4. 实验结果
| epoch-40-avg-15 | greedy search | modified beam search | fast beam search |
|---|---|---|---|
| baseline | 3.79 & 9.71 | 3.66 & 9.43 | 3.73 & 9.6 |
| with the gradient filter | 3.66 & 9.51 | 3.55 & 9.28 | 3.55 & 9.33 |
