
分享
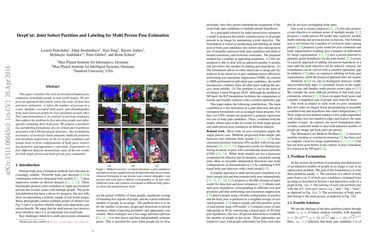
This paper considers the task of articulated human pose estimation of multiple people in real world images. We propose an approach that jointly solves the tasks of detection and pose estimation: it infers the number of persons in a scene, identifies occluded body parts, and disambiguates body parts between people in close proximity of each other. This joint formulation is in contrast to previous strategies, that address the problem by first detecting people and subsequently estimating their body pose. We propose a partitioning and labeling formulation of a set of body-part hypotheses generated with CNN-based part detectors. Our formulation, an instance of an integer linear program, implicitly performs non-maximum suppression on the set of part candidates and groups them to form configurations of body parts respecting geometric and appearance constraints. Experiments on four different datasets demonstrate state-of-the-art results for both single person and multi person pose estimation. Models and code available at http://pose.mpi-inf.mpg.de.
Emotion cause extraction (ECE), the task aimed at extracting the potential causes behind certain emotions in text, has gained much attention in recent years due to its wide applications. However, it suffers from two shortcomings: 1) the emotion must be annotated before cause extraction in ECE, which greatly limits its applications in real-world scenarios; 2) the way to first annotate emotion and then extract the cause ignores the fact that they are mutually indicative. In this work, we propose a new task: emotion-cause pair extraction (ECPE), which aims to extract the potential pairs of emotions and corresponding causes in a document. We propose a 2-step approach to address this new ECPE task, which first performs individual emotion extraction and cause extraction via multi-task learning, and then conduct emotion-cause pairing and filtering. The experimental results on a benchmark emotion cause corpus prove the feasibility of the ECPE task as well as the effectiveness of our approach.
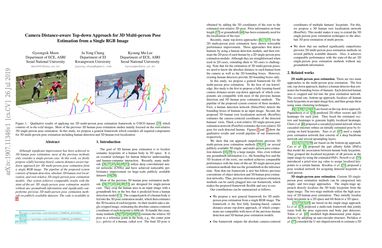
Although significant improvement has been achieved recently in 3D human pose estimation, most of the previous methods only treat a single-person case. In this work, we firstly propose a fully learning-based, camera distance-aware top-down approach for 3D multi-person pose estimation from a single RGB image. The pipeline of the proposed system consists of human detection, absolute 3D human root localization, and root-relative 3D single-person pose estimation modules. Our system achieves comparable results with the state-of-the-art 3D single-person pose estimation models without any groundtruth information and significantly outperforms previous 3D multi-person pose estimation methods on publicly available datasets. The code is available in https://github.com/mks0601/3DMPPE_ROOTNET_RELEASE , https://github.com/mks0601/3DMPPE_POSENET_RELEASE.
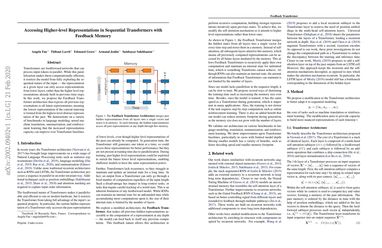
Transformers have been successfully applied to sequential, auto-regressive tasks despite being feedforward networks. Unlike recurrent neural networks, Transformers use attention to capture temporal relations while processing input tokens in parallel. While this parallelization makes them computationally efficient, it restricts the model from fully exploiting the sequential nature of the input. The representation at a given layer can only access representations from lower layers, rather than the higher level representations already available. In this work, we propose the Feedback Transformer architecture that exposes all previous representations to all future representations, meaning the lowest representation of the current timestep is formed from the highest-level abstract representation of the past. We demonstrate on a variety of benchmarks in language modeling, machine translation, and reinforcement learning that the increased representation capacity can create small, shallow models with much stronger performance than comparable Transformers.
Labeled data for imitation learning of theorem proving in large libraries of formalized mathematics is scarce as such libraries require years of concentrated effort by human specialists to be built. This is particularly challenging when applying large Transformer language models to tactic prediction, because the scaling of performance with respect to model size is quickly disrupted in the data-scarce, easily-overfitted regime. We propose PACT ({\bf P}roof {\bf A}rtifact {\bf C}o-{\bf T}raining), a general methodology for extracting abundant self-supervised data from kernel-level proof terms for co-training alongside the usual tactic prediction objective. We apply this methodology to Lean, an interactive proof assistant which hosts some of the most sophisticated formalized mathematics to date. We instrument Lean with a neural theorem prover driven by a Transformer language model and show that PACT improves theorem proving success rate on a held-out suite of test theorems from 32\% to 48\%.

Any-to-any voice conversion (VC) aims to convert the timbre of utterances from and to any speakers seen or unseen during training. Various any-to-any VC approaches have been proposed like AUTOVC, AdaINVC, and FragmentVC. AUTOVC, and AdaINVC utilize source and target encoders to disentangle the content and speaker information of the features. FragmentVC utilizes two encoders to encode source and target information and adopts cross attention to align the source and target features with similar phonetic content. Moreover, pre-trained features are adopted. AUTOVC used dvector to extract speaker information, and self-supervised learning (SSL) features like wav2vec 2.0 is used in FragmentVC to extract the phonetic content information. Different from previous works, we proposed S2VC that utilizes Self-Supervised features as both source and target features for VC model. Supervised phoneme posteriororgram (PPG), which is believed to be speaker-independent and widely used in VC to extract content information, is chosen as a strong baseline for SSL features. The objective evaluation and subjective evaluation both show models taking SSL feature CPC as both source and target features outperforms that taking PPG as source feature, suggesting that SSL features have great potential in improving VC.

Multi-head attention layers, as used in the Transformer neural sequence model, are a powerful alternative to RNNs for moving information across and between sequences. While training these layers is generally fast and simple, due to parallelizability across the length of the sequence, incremental inference (where such paralleization is impossible) is often slow, due to the memory-bandwidth cost of repeatedly loading the large "keys" and "values" tensors. We propose a variant called multi-query attention, where the keys and values are shared across all of the different attention "heads", greatly reducing the size of these tensors and hence the memory bandwidth requirements of incremental decoding. We verify experimentally that the resulting models can indeed be much faster to decode, and incur only minor quality degradation from the baseline.

Human-centric visual tasks have attracted increasing research attention due to their widespread applications. In this paper, we aim to learn a general human representation from massive unlabeled human images which can benefit downstream human-centric tasks to the maximum extent. We call this method SOLIDER, a Semantic cOntrollable seLf-supervIseD lEaRning framework. Unlike the existing self-supervised learning methods, prior knowledge from human images is utilized in SOLIDER to build pseudo semantic labels and import more semantic information into the learned representation. Meanwhile, we note that different downstream tasks always require different ratios of semantic information and appearance information. For example, human parsing requires more semantic information, while person re-identification needs more appearance information for identification purpose. So a single learned representation cannot fit for all requirements. To solve this problem, SOLIDER introduces a conditional network with a semantic controller. After the model is trained, users can send values to the controller to produce representations with different ratios of semantic information, which can fit different needs of downstream tasks. Finally, SOLIDER is verified on six downstream human-centric visual tasks. It outperforms state of the arts and builds new baselines for these tasks. The code is released in https://github.com/tinyvision/SOLIDER.

This paper highlights the importance of personalization in large language models and introduces the LaMP benchmark -- a novel benchmark for training and evaluating language models for producing personalized outputs. LaMP offers a comprehensive evaluation framework with diverse language tasks and multiple entries for each user profile. It consists of seven personalized tasks, spanning three text classification and four text generation tasks. We additionally propose two retrieval augmentation approaches that retrieve personal items from each user profile for personalizing language model outputs. To this aim, we study various retrieval models, including term matching, semantic matching, and time-aware methods. Extensive experiments on LaMP for zero-shot and fine-tuned language models demonstrate the efficacy of the proposed retrieval augmentation approach and highlight the impact of personalization in various natural language tasks.

We introduce CogVLM, a powerful open-source visual language foundation model. Different from the popular shallow alignment method which maps image features into the input space of language model, CogVLM bridges the gap between the frozen pretrained language model and image encoder by a trainable visual expert module in the attention and FFN layers. As a result, CogVLM enables deep fusion of vision language features without sacrificing any performance on NLP tasks. CogVLM-17B achieves state-of-the-art performance on 10 classic cross-modal benchmarks, including NoCaps, Flicker30k captioning, RefCOCO, RefCOCO+, RefCOCOg, Visual7W, GQA, ScienceQA, VizWiz VQA and TDIUC, and ranks the 2nd on VQAv2, OKVQA, TextVQA, COCO captioning, etc., surpassing or matching PaLI-X 55B. Codes and checkpoints are available at https://github.com/THUDM/CogVLM.

The softmax (also called softargmax) function is widely used in machine learning models to normalize real-valued scores into a probability distribution. To avoid floating-point overflow, the softmax function is conventionally implemented in three passes: the first pass to compute the normalization constant, and two other passes to compute outputs from normalized inputs. We analyze two variants of the Three-Pass algorithm and demonstrate that in a well-optimized implementation on HPC-class processors performance of all three passes is limited by memory bandwidth. We then present a novel algorithm for softmax computation in just two passes. The proposed Two-Pass algorithm avoids both numerical overflow and the extra normalization pass by employing an exotic representation for intermediate values, where each value is represented as a pair of floating-point numbers: one representing the "mantissa" and another representing the "exponent". Performance evaluation demonstrates that on out-of-cache inputs on an Intel Skylake-X processor the new Two-Pass algorithm outperforms the traditional Three-Pass algorithm by up to 28% in AVX512 implementation, and by up to 18% in AVX2 implementation. The proposed Two-Pass algorithm also outperforms the traditional Three-Pass algorithm on Intel Broadwell and AMD Zen 2 processors. To foster reproducibility, we released an open-source implementation of the new Two-Pass Softmax algorithm and other experiments in this paper as a part of XNNPACK library at GitHub.com/google/XNNPACK.

Click-through rate (CTR) prediction is one of the fundamental tasks for online advertising and recommendation. While multi-layer perceptron (MLP) serves as a core component in many deep CTR prediction models, it has been widely recognized that applying a vanilla MLP network alone is inefficient in learning multiplicative feature interactions. As such, many two-stream interaction models (e.g., DeepFM and DCN) have been proposed by integrating an MLP network with another dedicated network for enhanced CTR prediction. As the MLP stream learns feature interactions implicitly, existing research focuses mainly on enhancing explicit feature interactions in the complementary stream. In contrast, our empirical study shows that a well-tuned two-stream MLP model that simply combines two MLPs can even achieve surprisingly good performance, which has never been reported before by existing work. Based on this observation, we further propose feature gating and interaction aggregation layers that can be easily plugged to make an enhanced two-stream MLP model, FinalMLP. In this way, it not only enables differentiated feature inputs but also effectively fuses stream-level interactions across two streams. Our evaluation results on four open benchmark datasets as well as an online A/B test in our industrial system show that FinalMLP achieves better performance than many sophisticated two-stream CTR models. Our source code will be available at MindSpore/models.